
Accelerate AI Pipelines
Cut AI pipeline timelines with Kobayashi. Get NVIDIA-accelerated compute clusters up and running in hours (not weeks) — pre-configured with drivers, self-service access, and end-to-end engineering support.
Kobayashi AI Cloud
Build foundation models, scale global inference — launch AI faster, skip infrastructure hassle.
01Features
Cut AI pipeline timelines with Kobayashi. Get NVIDIA-accelerated compute clusters up and running in hours (not weeks) — pre-configured with drivers, self-service access, and end-to-end engineering support.
Build foundation models seamlessly with fault-tolerant infrastructure. Kobayashi’s node health monitoring and auto-repair keep your training jobs running — even when scaling to massive workloads.
Push your AI to its performance limits. Kobayashi minimizes infrastructure virtualization overhead to maximize Model FLOPS Utilization (MFU) — delivering results that match leading industry benchmarks.
Stay focused on high-impact AI work. Kobayashi’s integrated observability, managed orchestrators, and documented APIs eliminate DevOps friction from your entire ML lifecycle.
Scale safely in compliance-heavy environments. Kobayashi meets HIPAA, SOC 2, GDPR, and ISO 27001 standards — with privacy-first architecture and tenant-level isolation built in as default.
Work seamlessly with the tools you rely on. Kobayashi integrates with top ML platforms, tools, and services — so you can deliver actionable AI results from day one.
02Clusters
Accelerate your AI workloads with reliable NVIDIA GPU clusters on Kobayashi AI Cloud. Leverage bare-metal performance from the latest Blackwell & Hopper systems (connected via non-blocking NVIDIA InfiniBand) — all within a secure, fully virtualized cloud environment.
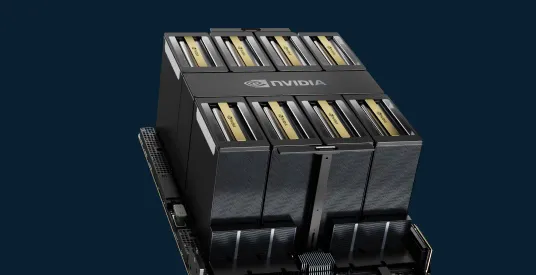
Air-cooled systems optimized for building & running reasoning LLMs, multi-modal models, and agentic AI.
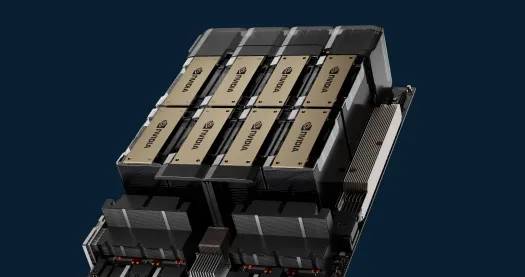
Extended GPU memory for consistent, predictable performance in LLM & multi-modal training/inference.
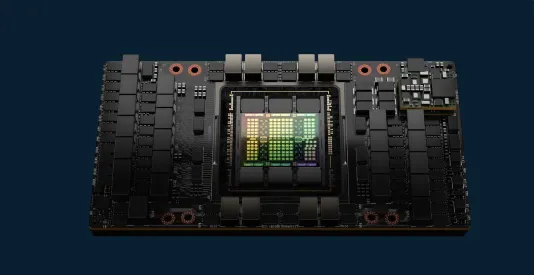
Cost-effective, robust GPU compute for large-scale foundational model building & serving.
03Platform
Our NVIDIA-accelerated AI Cloud platform includes fully managed Kubernetes & Slurm, granular observability, and topology-aware job scheduling. Your engineers can launch workloads right after provisioning — no tedious cluster configuration required.
04Storage
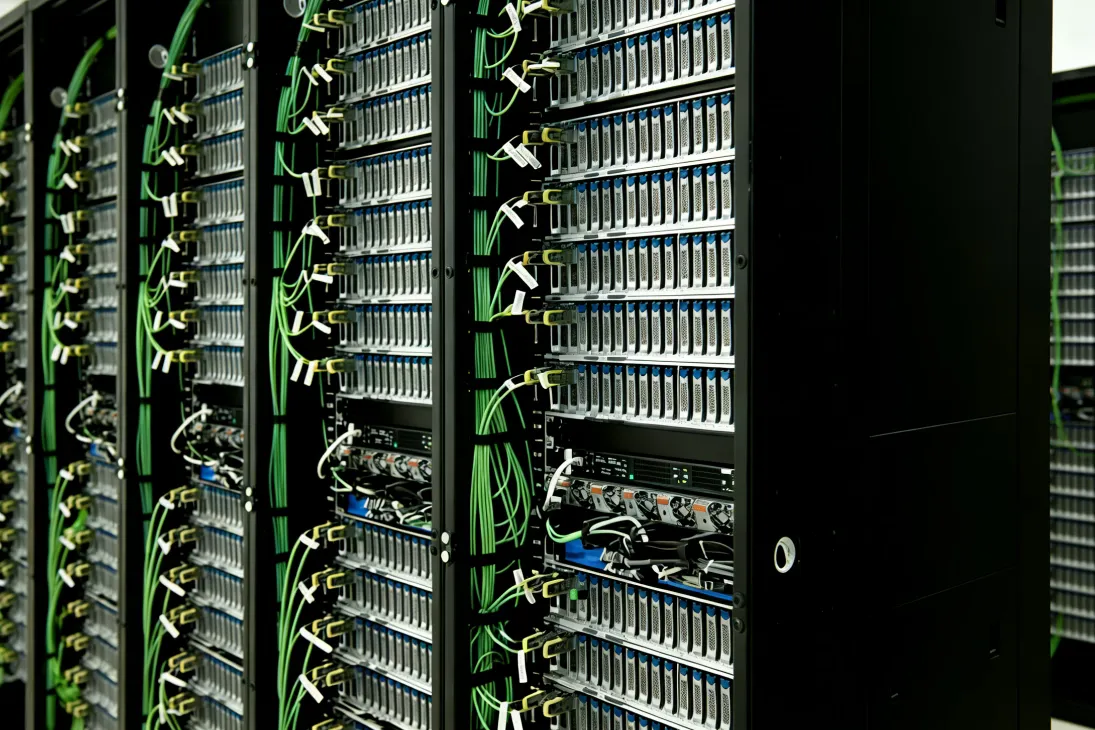
Our AI-tailored storage delivers up to 1TB/s shared filesystem read throughput and 2GB/s per GPU for object storage — engineered to integrate seamlessly with NVIDIA GPU platforms. Choose our optimized in-house solutions or leading partners (WEKA, VAST Data) for storage that scales with your workloads.
We use cookies to keep this site working and to understand how it’s used.